


Hardware · Arduino
What AI models can the Arduino Portenta X8 (2 GB) run?
- RAM
- 2.0 GB
- Usable for models
- 1.2 GB
- Memory bandwidth
- 12 GB/s
- Runs models on
- CPU cores
- Released
- 2022
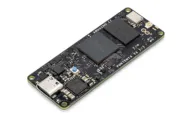
Models run on the CPU cores here, so the memory’s speed and how fast those cores can read it set the pace: small models (about 1-4B) are usable, bigger ones are slow. We plan around 1.2 GB of the 2.0 GB (what Linux leaves free for a model). No NPU. An STM32H747 microcontroller handles real-time I/O next to the Linux processor.
More about this hardware
| Maker | Arduino |
|---|---|
| Type | Single-board computer or edge AI board |
| Share of memory for models | 60% (what Linux typically leaves free on a board this size) |
| Chip | NXP i.MX 8M Mini |
| AI accelerator | No NPU. An STM32H747 microcontroller handles real-time I/O next to the Linux processor. |
| Boards with this chip | Arduino Portenta X8 |
| Memory type | 2 GB LPDDR4 |
| Bandwidth figure | 12.0 GB/s, estimated, see the note below |
| Note | 4× Cortex-A53 at 1.8 GHz running Linux with Docker containers. Only the smallest models (up to about 0.5B) are practical (estimate, assuming a 32-bit bus at 3000 MT/s). |
| Specifications | www.arduino.cc |
Apps that run models well on the Arduino Portenta X8 (2 GB)
Linux on ARM boards
1 product with the Arduino Portenta X8 (2 GB)
Best LLMs for the Arduino Portenta X8 (2 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 2Basic quality (D) · 2 of 100: how capable the model is at Q2_K, whatever it runs on. Match score 55/100 (quality, fit, speed and memory use) sets the ranking. | Falcon-H1 Tiny 90M Instruct | Q2_K | 0.8 GB | 44.8 tok/s | Runs great |
| 2Basic quality (D) · 2 of 100: how capable the model is at Q2_K, whatever it runs on. Match score 54/100 (quality, fit, speed and memory use) sets the ranking. | SmolLM2 135M Instruct | Q2_K | 0.9 GB | 31.0 tok/s | Runs great |
| 1Basic quality (D) · 1 of 100: how capable the model is at Q2_K, whatever it runs on. Match score 53/100 (quality, fit, speed and memory use) sets the ranking. | SmolLM 135M Instruct | Q2_K | 0.8 GB | 31.0 tok/s | Runs great |
| 7Basic quality (D) · 7 of 100: how capable the model is at Q2_K, whatever it runs on. Match score 53/100 (quality, fit, speed and memory use) sets the ranking. | LFM2.5 230M | Q2_K | 0.9 GB | 17.5 tok/s | Runs well |
| 9Basic quality (D) · 9 of 100: how capable the model is at Q2_K, whatever it runs on. Match score 52/100 (quality, fit, speed and memory use) sets the ranking. | LFM2.5 350M | Q2_K | 0.9 GB | 11.5 tok/s | Runs well |
| 18Basic quality (D) · 18 of 100: how capable the model is at Q2_K, whatever it runs on. Match score 52/100 (quality, fit, speed and memory use) sets the ranking. | Qwen3.5 0.8B | Q2_K | 1.1 GB | 4.6 tok/s | Slowtight fit |
| 8Basic quality (D) · 8 of 100: how capable the model is at Q2_K, whatever it runs on. Match score 51/100 (quality, fit, speed and memory use) sets the ranking. | Granite 4.0 H 350M | Q2_K | 0.9 GB | 11.9 tok/s | Runs well |
| 8Basic quality (D) · 8 of 100: how capable the model is at Q2_K, whatever it runs on. Match score 51/100 (quality, fit, speed and memory use) sets the ranking. | LFM2 350M | Q2_K | 0.9 GB | 11.5 tok/s | Runs well |
| 4Basic quality (D) · 4 of 100: how capable the model is at Q2_K, whatever it runs on. Match score 51/100 (quality, fit, speed and memory use) sets the ranking. | SmolVLM 256M Instruct | Q2_K | 1.0 GB | 15.5 tok/s | Runs well |
| 4Basic quality (D) · 4 of 100: how capable the model is at Q2_K, whatever it runs on. Match score 51/100 (quality, fit, speed and memory use) sets the ranking. | Gemma 3 270M | Q2_K | 0.8 GB | 14.9 tok/s | Runs well |
| 8Basic quality (D) · 8 of 100: how capable the model is at Q2_K, whatever it runs on. Match score 50/100 (quality, fit, speed and memory use) sets the ranking. | LFM2-VL 450M | Q2_K | 1.0 GB | 9.0 tok/s | Slow |
| 15Basic quality (D) · 15 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 50/100 (quality, fit, speed and memory use) sets the ranking. | LFM2 700M | Q3_K_M | 1.2 GB | 4.3 tok/s | Slowtight fit |


Best Image models for the Arduino Portenta X8 (2 GB)
None of the image models in our catalog fit in this much memory.
Best Video models for the Arduino Portenta X8 (2 GB)
None of the video models in our catalog fit in this much memory.
Best Decision models for the Arduino Portenta X8 (2 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 76Great quality (A) · 76 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 75/100 (quality, fit, speed and memory use) sets the ranking. | Llama Prompt Guard 2 86M | Q8_0 | 1.0 GB | 21.6 s | Very slow |
| 75Great quality (A) · 75 of 100: how capable the model is at Q6_K, whatever it runs on. Match score 73/100 (quality, fit, speed and memory use) sets the ranking. | mxbai-rerank-base v2 | Q6_K | 1.1 GB | 35.1 s | Very slowtight fit |
| 74Great quality (A) · 74 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 73/100 (quality, fit, speed and memory use) sets the ranking. | GLiClass ModernBERT Large v3 | Q8_0 | 1.1 GB | 15.5 s | Very slowtight fit |
| 70Great quality (A) · 70 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 72/100 (quality, fit, speed and memory use) sets the ranking. | GTE Reranker ModernBERT Base | Q8_0 | 0.8 GB | 11.6 s | Very slow |
| 68Good quality (B) · 68 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 72/100 (quality, fit, speed and memory use) sets the ranking. | Llama Prompt Guard 2 22M | Q8_0 | 0.7 GB | 5.5 s | Very slow |
| 72Great quality (A) · 72 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 72/100 (quality, fit, speed and memory use) sets the ranking. | DeBERTa v3 Large Zero-shot v2.0 | Q8_0 | 1.2 GB | 17.0 s | Very slowtight fit |
| 70Great quality (A) · 70 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 72/100 (quality, fit, speed and memory use) sets the ranking. | Jina Reranker v2 Base Multilingual | Q8_0 | 1.0 GB | 21.6 s | Very slow |
| 68Good quality (B) · 68 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 71/100 (quality, fit, speed and memory use) sets the ranking. | Granite Embedding Reranker English R2 | Q8_0 | 0.8 GB | 11.6 s | Very slow |


Estimates come from published hardware specs and our open formulas, not from running the model on your machine. Real speed varies with runtime, drivers and settings. Numbers marked “Measured” come from a linked benchmark.