

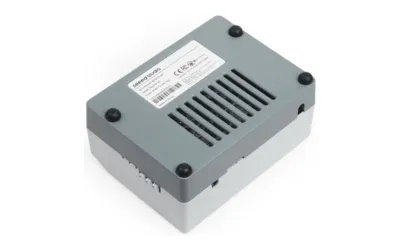
Hardware · Rockchip
What AI models can the Rockchip RK3576 (8 GB) run?
- RAM
- 8.0 GB
- Usable for models
- 6.4 GB
- Memory bandwidth
- 17 GB/s
- Runs models on
- CPU cores
- Released
- 2024
Models run on the CPU cores here, so the memory’s speed and how fast those cores can read it set the pace: small models (about 1-4B) are usable, bigger ones are slow. We plan around 6.4 GB of the 8.0 GB (what Linux leaves free for a model). 6 TOPS NPU (INT8), programmed with Rockchip’s RKNN and RKLLM toolkits. llama.cpp and Ollama use the CPU.
More about this hardware
| Maker | Rockchip |
|---|---|
| Type | Single-board computer or edge AI board |
| Share of memory for models | 80% (what Linux typically leaves free on a board this size) |
| Chip | Rockchip RK3576 |
| AI accelerator | 6 TOPS NPU (INT8), programmed with Rockchip’s RKNN and RKLLM toolkits. llama.cpp and Ollama use the CPU. |
| Boards with this chip | Seeed reComputer RK3576 · Radxa ROCK 4D · FriendlyElec NanoPi M5 · Luckfox Omni3576 · KICKPI K7 |
| Memory type | LPDDR4X-4266 or LPDDR5-5500, 32-bit (17-22 GB/s) |
| Bandwidth figure | 17.1 GB/s, the chip’s rated memory speed |
| Note | 4× Cortex-A72 at 2.2 GHz plus 4× Cortex-A53, Mali-G52 GPU, up to 16 GB. Half the memory bus of the RK3588 (32-bit), so models generate at roughly half its speed. Speeds assume llama.cpp on the CPU at about 45% of the rated memory speed (estimate). |
| Specifications | www.rock-chips.com |
Apps that run models well on the Rockchip RK3576 (8 GB)
Linux on ARM boards
1 product with the Rockchip RK3576 (8 GB)
Best LLMs for the Rockchip RK3576 (8 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 64Good quality (B) · 64 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 73/100 (quality, fit, speed and memory use) sets the ranking. | Nanbeige4.2 3B | Q4_K_M | 5.1 GB | 3.1 tok/s | Slow |
| 64Good quality (B) · 64 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 72/100 (quality, fit, speed and memory use) sets the ranking. | Nemotron Labs Dory 1.0 4B | Q4_K_M | 4.0 GB | 3.3 tok/s | Slow |
| 61Good quality (B) · 61 of 100: how capable the model is at Q6_K, whatever it runs on. Match score 72/100 (quality, fit, speed and memory use) sets the ranking. | Gemma 4 E2B | Q6_K | 5.4 GB | 4.0 tok/s | Slow |
| 65Good quality (B) · 65 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 71/100 (quality, fit, speed and memory use) sets the ranking. | MiMo V2.6 Distill Qwen 9B | Q3_K_M | 6.0 GB | 1.8 tok/s | Very slowtight fit |
| 65Good quality (B) · 65 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 71/100 (quality, fit, speed and memory use) sets the ranking. | SenseNova Loop 9B Preview | Q3_K_M | 6.3 GB | 1.8 tok/s | Very slowtight fit |
| 62Good quality (B) · 62 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 71/100 (quality, fit, speed and memory use) sets the ranking. | Spark-X2.6 4B | Q4_K_M | 3.9 GB | 3.2 tok/s | Slow |
| 64Good quality (B) · 64 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 71/100 (quality, fit, speed and memory use) sets the ranking. | Ornith 1.5 9B | Q3_K_M | 6.1 GB | 1.8 tok/s | Very slowtight fit |
| 50Fair quality (C) · 50 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 71/100 (quality, fit, speed and memory use) sets the ranking. | Ling 3.0 Tiny (8B-A1.3B) | Q3_K_M | 5.2 GB | 12.5 tok/s | Runs well |
| 58Good quality (B) · 58 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 71/100 (quality, fit, speed and memory use) sets the ranking. | Nemotron 3.5 Bolt E4B | Q3_K_M | 5.2 GB | 3.8 tok/s | Slow |
| 63Good quality (B) · 63 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 70/100 (quality, fit, speed and memory use) sets the ranking. | Qwen3.5 9B | Q3_K_M | 6.1 GB | 1.8 tok/s | Very slowtight fit |
| 63Good quality (B) · 63 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 70/100 (quality, fit, speed and memory use) sets the ranking. | Ornith 1.0 9B | Q3_K_M | 6.1 GB | 1.8 tok/s | Very slowtight fit |
| 57Good quality (B) · 57 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 70/100 (quality, fit, speed and memory use) sets the ranking. | Gemma 4 E4B | Q3_K_M | 5.2 GB | 3.8 tok/s | Slow |


Best Image models for the Rockchip RK3576 (8 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 84Great quality (A) · 84 of 100: how capable the model is at Q4 GGUF, whatever it runs on. Match score 72/100 (quality, fit, speed and memory use) sets the ranking. | FLUX 3 Image Klein | Q4 GGUF | 5.7 GB | 21.8 min | Very slowtight fit · encoder unloaded after use |
| 76Great quality (A) · 76 of 100: how capable the model is at FP8, whatever it runs on. Match score 71/100 (quality, fit, speed and memory use) sets the ranking. | FLUX.2 [klein] 4B | FP8 | 6.2 GB | 2.9 min | Very slowtight fit · encoder unloaded after use |
| 76Great quality (A) · 76 of 100: how capable the model is at Q4 GGUF, whatever it runs on. Match score 70/100 (quality, fit, speed and memory use) sets the ranking. | MOSS-Image SFT | Q4 GGUF | 5.4 GB | 53.5 min | Very slowencoder unloaded after use |
| 78Great quality (A) · 78 of 100: how capable the model is at Q4 GGUF, whatever it runs on. Match score 70/100 (quality, fit, speed and memory use) sets the ranking. | Z-Image Turbo | Q4 GGUF | 6.1 GB | 9.5 min | Very slowtight fit · encoder unloaded after use |
| 76Great quality (A) · 76 of 100: how capable the model is at Q4 GGUF, whatever it runs on. Match score 68/100 (quality, fit, speed and memory use) sets the ranking. | Z-Image | Q4 GGUF | 6.1 GB | 64.9 min | Very slowtight fit · encoder unloaded after use |
| 39Basic quality (D) · 39 of 100: how capable the model is at FP8, whatever it runs on. Match score 67/100 (quality, fit, speed and memory use) sets the ranking. | SDXL Turbo | FP8 | 4.2 GB | 25 s | Runs well |


Best Video models for the Rockchip RK3576 (8 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 35Basic quality (D) · 35 of 100: how capable the model is at FP16, whatever it runs on. Match score 59/100 (quality, fit, speed and memory use) sets the ranking. | AnimateDiff v3 (SD 1.5) | FP16 | 4.7 GB | 60.6 min | Very slow |
| 49Fair quality (C) · 49 of 100: how capable the model is at FP8, whatever it runs on. Match score 58/100 (quality, fit, speed and memory use) sets the ranking. | LTX-Video 2B | FP8 | 6.1 GB | 71.6 min | Very slowtight fit · encoder unloaded after use |
| 53Fair quality (C) · 53 of 100: how capable the model is at FP8, whatever it runs on. Match score 50/100 (quality, fit, speed and memory use) sets the ranking. | CogVideoX 5B | FP8 | 5.9 GB | 10.6 h | Very slowtight fit · CPU offload |
| 53Fair quality (C) · 53 of 100: how capable the model is at FP8, whatever it runs on. Match score 50/100 (quality, fit, speed and memory use) sets the ranking. | CogVideoX 5B I2V | FP8 | 6.1 GB | 10.6 h | Very slowtight fit · CPU offload |
| 53Fair quality (C) · 53 of 100: how capable the model is at FP8, whatever it runs on. Match score 50/100 (quality, fit, speed and memory use) sets the ranking. | Wan 2.1 T2V 1.3B | FP8 | 6.0 GB | 14.2 h | Very slowtight fit · CPU offload |


Best Decision models for the Rockchip RK3576 (8 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 78Great quality (A) · 78 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 83/100 (quality, fit, speed and memory use) sets the ranking. | OpenAI Privacy Filter | Q8_0 | 2.4 GB | 210 ms | Runs well |
| 89Excellent quality (A+) · 89 of 100: how capable the model is at Q6_K, whatever it runs on. Match score 80/100 (quality, fit, speed and memory use) sets the ranking. | Qwen3 Reranker 4B | Q6_K | 4.7 GB | 30.9 s | Very slow |
| 86Excellent quality (A+) · 86 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 80/100 (quality, fit, speed and memory use) sets the ranking. | Jina Reranker v3.5 | Q8_0 | 2.0 GB | 4.6 s | Very slow |
| 87Excellent quality (A+) · 87 of 100: how capable the model is at Q6_K, whatever it runs on. Match score 80/100 (quality, fit, speed and memory use) sets the ranking. | zerank-2 | Q6_K | 4.7 GB | 30.9 s | Very slow |
| 84Great quality (A) · 84 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 80/100 (quality, fit, speed and memory use) sets the ranking. | Jina Reranker v3 | Q8_0 | 2.0 GB | 4.6 s | Very slow |
| 86Excellent quality (A+) · 86 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 79/100 (quality, fit, speed and memory use) sets the ranking. | Shieldstral 1.0 3B | Q8_0 | 5.4 GB | 29.8 s | Very slow |
| 80Great quality (A) · 80 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 79/100 (quality, fit, speed and memory use) sets the ranking. | GLiNER2.5 Decide | Q8_0 | 1.2 GB | 2.0 s | Very slow |
| 80Great quality (A) · 80 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 78/100 (quality, fit, speed and memory use) sets the ranking. | FRIDA-Decisions | Q8_0 | 1.7 GB | 3.4 s | Very slow |


Estimates come from published hardware specs and our open formulas, not from running the model on your machine. Real speed varies with runtime, drivers and settings. Numbers marked “Measured” come from a linked benchmark.