

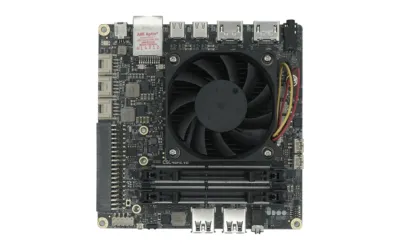
Hardware · AMD
What AI models can the UDOO BOLT V8 (8 GB) run?
- Unified memory
- 8.0 GB
- Usable for models
- 4.0 GB
- Memory bandwidth
- 38 GB/s
- Runs models on
- GPU (Vulkan)
- Released
- 2019
Models run on the GPU (Vulkan) here, sharing the board’s memory with the system. We plan around 4.0 GB of the 8.0 GB (what the operating system leaves free for a model). Radeon Vega 8 graphics (8 compute units); no NPU. llama.cpp uses it through Vulkan (ROCm doesn’t support this GPU).
More about this hardware
| Maker | AMD |
|---|---|
| Type | Single-board computer or edge AI board |
| GPU share of memory | 50% (what the GPU can typically be given for a model) |
| Chip | AMD Ryzen Embedded V1605B |
| AI accelerator | Radeon Vega 8 graphics (8 compute units); no NPU. llama.cpp uses it through Vulkan (ROCm doesn’t support this GPU). |
| Boards with this chip | UDOO BOLT V8 · UDOO BOLT GEAR |
| Memory type | DDR4-2400, two SO-DIMM slots (dual channel) |
| Bandwidth figure | 38.4 GB/s, the chip’s rated memory speed |
| Note | 4-core, 8-thread Ryzen Embedded V1605B, up to 32 GB in two SO-DIMMs, plus an Arduino Leonardo-compatible microcontroller. We assume the GPU can use about half of the RAM. GPU figure from 8 CUs at 1.1 GHz. |
| Specifications | shop.seco.com |
Apps that run models well on the UDOO BOLT V8 (8 GB)

1 product with the UDOO BOLT V8 (8 GB)
Best LLMs for the UDOO BOLT V8 (8 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 64Good quality (B) · 64 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 75/100 (quality, fit, speed and memory use) sets the ranking. | Nemotron Labs Dory 1.0 4B | Q4_K_M | 3.8 GB | 10.2 tok/s | Runs welltight fit |
| 57Good quality (B) · 57 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 75/100 (quality, fit, speed and memory use) sets the ranking. | MiniCPM5 2B | Q4_K_M | 2.8 GB | 16.1 tok/s | Runs well |
| 52Fair quality (C) · 52 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 73/100 (quality, fit, speed and memory use) sets the ranking. | Gemma 4 E2B | Q3_K_M | 3.5 GB | 22.8 tok/s | Runs welltight fit |
| 55Good quality (B) · 55 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 73/100 (quality, fit, speed and memory use) sets the ranking. | Spark-X2.6 4B | Q3_K_M | 3.2 GB | 12.8 tok/s | Runs well |
| 42Fair quality (C) · 42 of 100: how capable the model is at Q5_K_M, whatever it runs on. Match score 73/100 (quality, fit, speed and memory use) sets the ranking. | Unlimited OCR 2 (3B-A0.6B) | Q5_K_M | 3.8 GB | 46.7 tok/s | Runs welltight fit |
| 53Fair quality (C) · 53 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 72/100 (quality, fit, speed and memory use) sets the ranking. | LFM3 1.7B | Q4_K_M | 2.1 GB | 23.5 tok/s | Runs well |
| 38Basic quality (D) · 38 of 100: how capable the model is at Q5_K_M, whatever it runs on. Match score 71/100 (quality, fit, speed and memory use) sets the ranking. | Unlimited OCR (3B-A0.6B) | Q5_K_M | 3.8 GB | 46.7 tok/s | Runs welltight fit |
| 51Fair quality (C) · 51 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 71/100 (quality, fit, speed and memory use) sets the ranking. | TMax 4B | Q3_K_M | 3.3 GB | 12.5 tok/s | Runs well |
| 52Fair quality (C) · 52 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 70/100 (quality, fit, speed and memory use) sets the ranking. | Qwen3.5 4B | Q3_K_M | 3.5 GB | 11.3 tok/s | Runs welltight fit |
| 47Fair quality (C) · 47 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 69/100 (quality, fit, speed and memory use) sets the ranking. | LFM3-VL 2B | Q4_K_M | 2.2 GB | 21.1 tok/s | Runs well |
| 38Basic quality (D) · 38 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 69/100 (quality, fit, speed and memory use) sets the ranking. | TeleOCR | Q4_K_M | 2.7 GB | 28.6 tok/s | Runs well |
| 50Fair quality (C) · 50 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 69/100 (quality, fit, speed and memory use) sets the ranking. | Agents-A1 4B | Q3_K_M | 3.4 GB | 11.6 tok/s | Runs welltight fit |


Best Image models for the UDOO BOLT V8 (8 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 76Great quality (A) · 76 of 100: how capable the model is at FP8, whatever it runs on. Match score 68/100 (quality, fit, speed and memory use) sets the ranking. | FLUX.2 [klein] 4B | FP8 | 3.5 GB | 26 s | Runs welltight fit · CPU offload |
| 30Basic quality (D) · 30 of 100: how capable the model is at FP16, whatever it runs on. Match score 68/100 (quality, fit, speed and memory use) sets the ranking. | LCM DreamShaper v7 | FP16 | 2.8 GB | 5.6 s | Runs great |
| 84Great quality (A) · 84 of 100: how capable the model is at Q4 GGUF, whatever it runs on. Match score 68/100 (quality, fit, speed and memory use) sets the ranking. | FLUX 3 Image Klein | Q4 GGUF | 3.4 GB | 3.3 min | Very slowCPU offload |
| 42Fair quality (C) · 42 of 100: how capable the model is at FP16, whatever it runs on. Match score 68/100 (quality, fit, speed and memory use) sets the ranking. | Realistic Vision V5.1 | FP16 | 2.8 GB | 27 s | Runs well |
| 28Basic quality (D) · 28 of 100: how capable the model is at FP16, whatever it runs on. Match score 67/100 (quality, fit, speed and memory use) sets the ranking. | SD Turbo | FP16 | 3.3 GB | 1.8 s | Runs great |
| 40Fair quality (C) · 40 of 100: how capable the model is at FP16, whatever it runs on. Match score 67/100 (quality, fit, speed and memory use) sets the ranking. | DreamShaper 8 | FP16 | 2.8 GB | 27 s | Runs well |


Best Video models for the UDOO BOLT V8 (8 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 35Basic quality (D) · 35 of 100: how capable the model is at FP16, whatever it runs on. Match score 51/100 (quality, fit, speed and memory use) sets the ranking. | AnimateDiff v3 (SD 1.5) | FP16 | 2.6 GB | 9.7 min | Runs wellCPU offload |

Best Decision models for the UDOO BOLT V8 (8 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 80Great quality (A) · 80 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 90/100 (quality, fit, speed and memory use) sets the ranking. | GLiNER2.5 Decide | Q8_0 | 1.2 GB | 102 ms | Runs great |
| 74Great quality (A) · 74 of 100: how capable the model is at F16, whatever it runs on. Match score 88/100 (quality, fit, speed and memory use) sets the ranking. | GLiClass ModernBERT Large v3 | F16 | 1.5 GB | 96 ms | Runs great |
| 76Great quality (A) · 76 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 88/100 (quality, fit, speed and memory use) sets the ranking. | Llama Prompt Guard 2 86M | Q8_0 | 1.0 GB | 116 ms | Runs great |
| 86Excellent quality (A+) · 86 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 88/100 (quality, fit, speed and memory use) sets the ranking. | Jina Reranker v3.5 | Q8_0 | 1.8 GB | 253 ms | Runs well |
| 78Great quality (A) · 78 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 88/100 (quality, fit, speed and memory use) sets the ranking. | OpenAI Privacy Filter | Q8_0 | 2.4 GB | 14 ms | Runs great |
| 80Great quality (A) · 80 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 87/100 (quality, fit, speed and memory use) sets the ranking. | FRIDA-Decisions | Q8_0 | 1.7 GB | 168 ms | Runs well |
| 72Great quality (A) · 72 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 87/100 (quality, fit, speed and memory use) sets the ranking. | DeBERTa v3 Large Zero-shot v2.0 | Q8_0 | 1.2 GB | 92 ms | Runs great |
| 84Great quality (A) · 84 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 87/100 (quality, fit, speed and memory use) sets the ranking. | Jina Reranker v3 | Q8_0 | 1.8 GB | 253 ms | Runs well |


Estimates come from published hardware specs and our open formulas, not from running the model on your machine. Real speed varies with runtime, drivers and settings. Numbers marked “Measured” come from a linked benchmark.